 ETHORITY®

AI Trust Pilot
Six weeks, one use case. Then decide.
Find out whether your use case works in a bounded six-week pilot.
€25,000 net · one-time
One-time · six weeks. Work starts after confirmed payment and agreement on the starting information. ETHORITY confirms the start date. You approve the pilot goals, evaluation criteria and stop rules before testing begins.

What you receive
A six-week supervised pilot of one use case and a final decision package with the evidence behind it.
Tell us the problem, the outcome you want and who we can speak with. Share existing examples or documents if available. You do not need a finished system or access to your live systems to start. ETHORITY recommends and prepares the appropriate test setup.
The ETHORITY Promise
The ETHORITY Promise
We make the value clear. We take responsibility for our delivery. We make results transparent.
- A specific expected outcome, with its basis and assumptions.
- Defined deliverables, price, timing and acceptance criteria.
- Supporting evidence, accountable ownership and measurement where included.
You receive a clear recommendation, an agreed delivery commitment and transparent results. We explain the value you can expect, the basis for that assessment and what ETHORITY takes responsibility for.
- Expected value
- After six weeks, you receive our recommendation to continue, redesign, expand or stop, based on the test results. We name their limits and any evidence still needed.
- Your deliverable
- A decision package – continue, redesign, expand or stop – with the measurements compared against the week-1 baseline.
- Responsibility
- ETHORITY reviews the pilot with you every week and measures it against the acceptance and stop conditions agreed in week 2.
- Evidence
- The baseline before AI is involved, the weekly review records and the full measurement series up to the decision, each labelled with its test setup.
- Fixed price
- €25,000 plus VAT, one-time
- Duration
- six weeks from the start date ETHORITY confirms after payment and agreement on the starting information
The value receipt runs through the whole assignment: the expected value before you order, then the agreed commitment, and the proof on delivery.
Scenario figures are assumed; your own figures are established in your assignment.Scope, responsibilities and evidence
- 1
- use case in one accountable departmentOffer terms →
- Week 1
- baseline set before AI is involved, source statedOffer terms →
- Week 2
- acceptance and stop conditions agreedOffer terms →
Your decision at a glance
- You receive
- A six-week supervised pilot of one use case and a final decision package with the evidence behind it.
- Price
- €25,000 net · one-time
- Duration
- Six weeks. Work starts after confirmed payment and agreement on the starting information. ETHORITY confirms the start date. You approve the pilot goals, evaluation criteria and stop rules before testing begins.
- What we need from you to get started
- Tell us the problem, the outcome you want and who we can speak with. Share existing examples or documents if available. You do not need a finished system or access to your live systems to start. ETHORITY recommends and prepares the appropriate test setup.
- Next step
- Discuss a pilot in a 30-minute call.
Tell us the problem.
What ETHORITY delivers
- A pilot designed around your business goal, with agreed success criteria and stop conditions
- The appropriate test setup – when suitable, an ETHORITY sandbox separate from your systems – and the pilot system built or configured to the agreed scope
- Testing, reviews and analysis against a clearly identified baseline
- A final recommendation with results, open points and the next step
What we need from you to get started
- Tell us the problem, the outcome you want and who we can speak with. Share existing examples or documents if available. You do not need a finished system or access to your live systems to start. ETHORITY recommends and prepares the appropriate test setup.
Tell us the problem, the outcome you want and who we can speak with. Share existing examples or documents if available. You do not need a finished system or access to your live systems to start. ETHORITY recommends and prepares the appropriate test setup.
Don’t know something yet? Say so. ETHORITY clarifies it with you as part of the work.
Your decision
- Agree the pilot goal, the stop rules and the proposed test setup
- Review the results and ask questions
- Continue, redesign, expand or stop
- Authorise separately: use of your data, connection to your systems, spending and deployment
six weeks from the start date ETHORITY confirms after payment and agreement on the starting information
- Goals, limits and stop rules agreed before the pilot starts.
- Weekly reviews against a baseline set before AI is involved, with its source stated.
- A final decision package: continue, redesign, expand or stop.
What you receive
- Pilot design: scope, intended outcome, boundaries, acceptance and stop conditions.
- Test setup and pilot system: the test setup ETHORITY recommends, and the pilot system built or configured to the agreed scope.
- ETHORITY AI Trust Chain, evidence register and owner model for the pilot, built from the Trust Record.
- Documented review of changes, open points and decision conditions during the pilot. Sten Franke is responsible for the review and signs off the decision package.
- Final decision package: continue, redesign, expand or stop, with the evidence behind it.
- Handover with a continuation plan.
Who it is for
An executive sponsor and a department that want to test one AI use case before committing budget, customers or staff to it. Often the next step after an AI Trust Record or an Opportunity Case that answered "test first".
The question it answers
Does this AI use case work in our operation, under our conditions, well enough to continue?
How it works
- 1
Week 1 Pilot contract; ETHORITY recommends the test setup and sets the baseline: what performance looks like today, before AI is involved, with its source stated.
- 2
Week 2 Pilot design session: ETHORITY proposes scope, boundaries, the test setup, acceptance and stop conditions; sponsor and owner approve them.
- 3
Weeks 3–5 Pilot run; ETHORITY builds or configures the pilot system, tests it in the agreed test setup and reviews evidence, changes and open points every week.
- 4
Week 6 ETHORITY leads the final decision session and hands over a continuation plan; you decide.
Even without access to your systems, we can first develop and test your solution in a separate environment.
ETHORITY recommends the least intrusive test setup that is still sufficient for your decision. The four routes are alternatives, not stages. You can decline access to your systems and still receive a usable result. If your decision needs evidence from live operation, ETHORITY explains what remains open and proposes how to confirm it later.
ETHORITY sandbox
We build and test in a separate environment with synthetic examples and simulated connections.
Access to your systems: None
What the result shows: Technical results for the stated test setup. Financial effects remain estimates based on explicit assumptions until measurements from actual operations establish the benefits realised.
Approved sample data
ETHORITY defines the sample needed and prepares the sampling or export instructions. Your authorised team supplies the data and approves its use. We run the agreed tests with this data.
Access to your systems: No connection and no credentials
What the result shows: How the solution performs with your sample. We explain the sample’s limits and what a live connection would require.
Your own test environment
We supply the system, configuration, test plan and support; your IT team runs the system and the tests inside your environment.
Access to your systems: No direct access for ETHORITY
What the result shows: Results in your test environment, backed by the agreed logs. ETHORITY remains responsible for the engineering and the evaluation.
Connected pilot
We connect to the systems you explicitly authorise, with agreed users, operations and stop conditions.
Access to your systems: Only the access authorised for this pilot
What the result shows: Measured results within the pilot’s limits. A wider rollout and lasting business benefit need their own evidence.
Packages and price
AI Trust Pilot
€25,000 net · one-time
One agreed use case, one department, weekly reviews, final decision package.
Request scope and delivery
See what this package includes →Terms
Net. Work starts after confirmed payment and agreement on the starting information. ETHORITY confirms the start date. You approve the pilot goals, evaluation criteria and stop rules before testing begins. To start, tell us the problem, the outcome you want and who we can speak with. A finished system or access to your live systems is not required: ETHORITY recommends and prepares the appropriate test setup.
Boundary
One use case: design, test setup, the pilot system built or configured to the agreed scope, standard protection and evidence controls, evaluation, review and decision. Larger development, production rollout, ongoing operation, certification and regulatory steps are scoped separately with the appropriate partners.
Who is accountable for the result
Sten Franke
Founder & CEO
Sten Franke designs and builds AI systems, from model testing and cloud setup to the interfaces people use. He connects business decisions, software architecture and practical implementation.
AI architecture · Model testing · Cloud engineering · UX
His work spans programming, LLM evaluation, Google Cloud and AWS environments, and web applications built with Next.js and React. He connects business requirements, software architecture and practical implementation. Creator of the Good AI Prism, he brings market intelligence into AI decisions. Earlier, he created the Social Media Prisma, led a BVDW Social Media working group and contributed to its Social Media Kompass. His entrepreneurial work includes ethority, Gridpatrol and mediatime, following a practical foundation in electronics and industrial robotics.
sten@ethority.aiSten Franke frames the assignment, interprets the findings and signs off on the final recommendations.
Real offerings we compare against
Pilots run on real products. Three profiles show the operating facts a pilot design records: Genesys Cloud AI in contact centres, Slite Agent for team knowledge and Spendesk AI Connect for finance.
Genesys Cloud AI
Genesys · Product
A contact-centre platform with AI agents (“Agentic Virtual Agent”), copilots for agents and supervisors, and AI Studio.
- Published price
- How it is billed
- Where data is stored
- Does it train AI on your data?
Slite Agent
Slite · Agent
According to Slite: “Scale AI across your company with Slite agent that delivers trusted answers, drafts documentation and proposes updates for your team to approve.”
- Published price
- How it is billed
- Where data is stored
- Does it train AI on your data?
Spendesk AI Connect
Spendesk · Product
Connects Spendesk spend data to AI assistants so finance teams can search, analyse and report on spend in plain language.
- Published price
- How it is billed
- Where data is stored
- Does it train AI on your data?
Read before you decide
Why pilots stall: trusting AI and going all-in are one job.
AI does not scale by itself. Redesign the work.
Start with one objective, choose the simplest approach for each task and measure the cost of every result you accept.
See the map on one page →
Trusting AI and going all-in are one job.
Why speed and responsible AI are no longer competing choices. An essay by Sten Franke.
See the map on one page →
Saved hours are not AI value.
Separate a better task, freed-up time and a business result, so you can show the value AI really delivers.
See the map on one page →Want a preview?
Our examples and calculators show how we assess value and assumptions. Using them is optional. For your assignment, ETHORITY does the preparation and the assessment.
Below, Capacity Conversion shows how much review time per AI answer the case can carry; on that basis ETHORITY agrees the pilot’s stop rules with you in week 2. All tools sit in the ETHORITY AI calculator suite.
Capacity Conversion calculator
Shows how much of the time AI saves becomes money, including the 36-second checking test as a Scenario.
Pilot version · Scenario calculator
Open the calculator →Total Cost of AI Ownership calculator
All six cost blocks over 36 months, compared with today's cost per accepted result, and the month the investment pays back.
Pilot version · Scenario calculator
Open the calculator →Compare three offerings
Puts two to four offerings side by side in the same units, each fact with its source and the date it was checked.
Questions buyers ask
Who builds the system?
ETHORITY designs, builds or configures, tests and evaluates your pilot within the agreed scope. Production rollout and wider integrations are agreed separately.
What if the pilot ends in stop or redesign?
Then the decision package says stop or redesign, with the evidence. That is a successful pilot.
Do we need an AI Trust Record first?
It is the starting structure. Where none exists, its core is built in week one.
Can we extend it?
A longer or multi-department pilot is scoped separately.
How do we know the pilot worked?
Success and stop conditions are agreed before it starts, and the decision package measures the pilot against them and the week-one baseline.
Test in a controlled environment. Decide with evidence.
ETHORITY builds or configures your pilot solution in the agreed test environment. Before work starts, we agree with you who may access which data, which actions are permitted and how results will be tested and recorded. You receive our recommendation with its supporting evidence. Connecting to your live systems requires your explicit approval.
| What you receive | How ETHORITY provides it |
|---|---|
| An agreed test setup | The test setup and access controls are specified for your assignment, with their limits and verification recorded before testing. |
| AI working within agreed limits | Permitted actions, approved connections, resource limits and stop conditions |
| The ETHORITY AI Trust Chain | Business goal → accountable owner → data and system → evidence → review → decision |
| Traceable result records | Versioned evidence that names its source, the test setup, the data origin and the reviewer |
| A decision you can act on | ETHORITY’s recommendation, the supporting results, their limits and the next steps you authorise separately |
The controls for your assignment, and any limits, are named in the proposal before you sign.
You receive the reviewed result and its evidence history. The proposal identifies the controls to be used and verified for your assignment.
One use case, one working pilot, one decision.
ETHORITY defines this scope with you and names each point in the proposal before you sign. The price for the six weeks remains €25,000 plus VAT.
| Included | Named in the proposal before you sign |
|---|---|
| One business use case in the agreed department | Outcome, users, baseline, acceptance criteria and stop rules |
| One configured solution or working pilot implementation | What it does, the inputs and outputs it supports, and its boundaries |
| One agreed primary test setup | ETHORITY sandbox, approved sample data, your own test environment or a bounded connected pilot |
| Agreed interfaces and data preparation | Which connections are real and which simulated, sample and volume limits, dependencies |
| Evaluation and review | Test coverage, evaluation method, the named reviewer and weekly reviews |
| Standard protection and evidence controls | The controls tested for your assignment, with any limits declared in the proposal |
| Final decision package and handover | Findings, open points, the recommended next step, the agreed software and configuration, and your usage rights |
Scoped separately when needed: larger custom development, further workflows, production rollout, ongoing hosting and support, private-cloud or on-premises requirements and external assurance. The pilot includes the agreed working implementation, access controls and evidence records; their tested limits are documented for your assignment.
ETHORITY · LONG READ
A pilot should end in a decision you can act on.
Many AI pilots end in a presentation and no decision. The difference is whether success and stop conditions were agreed before the first live case.
A pilot ends in a decision when success and stop conditions are agreed before the pilot starts.
Pilots fail in a particular way. They start with enthusiasm, run for a few months, produce a demo that impresses the steering committee and then stall. Nobody agreed in advance what result would justify scaling, so nobody can say whether the result was good enough. The insight on whether to go all in calls this the gap between a trial and a decision.
The AI Trust Pilot is designed to close that gap. It runs one agreed use case in one accountable department for six weeks. Before the pilot starts, the sponsor and the operational owner agree the scope, the intended outcome, the boundaries, and the acceptance and stop conditions. ETHORITY sets the baseline first and states where it comes from, so everyone knows what the pilot compares AI against.
The pilot uses the structure of the AI Trust Record: the ETHORITY AI Trust Chain, which links outcome, owner, data, AI component, human authority, evidence and review. During the pilot, that chain is live. Each week, ETHORITY reviews the evidence, the changes and the open points, and records whether the decision conditions are moving towards or away from being met.
The last week produces a decision package: continue, redesign, expand or stop. Each answer comes with its evidence. A stop is the pilot doing its job: it saves the budget that a full rollout would have consumed.
The pilot is deliberately bounded: it answers one question in an agreed test setup and hands over a plan for what comes next. For organisations where AI does not scale by itself, that bounded answer is the step that releases the budget, or saves it.
Sources and further reading
Scenario
A worked example
- The questionOne use case. Real conditions. Six weeks.
- Before the startGoals, limits and stop rules agreed upfront.
- During the pilotChanges and open points are reviewed independently.
- The decisionContinue, redesign, expand or stop, on evidence.
- Your next stepA personal recommendation from Sten Franke for what to do next.
From the deliverable
AI Trust Pilot
A six-week supervised pilot of one use case and a final decision package with the evidence behind it.
Explore the evidence and full sample pages
You decide on the next engagement; ETHORITY scopes the delivery with you.
Read the example as text
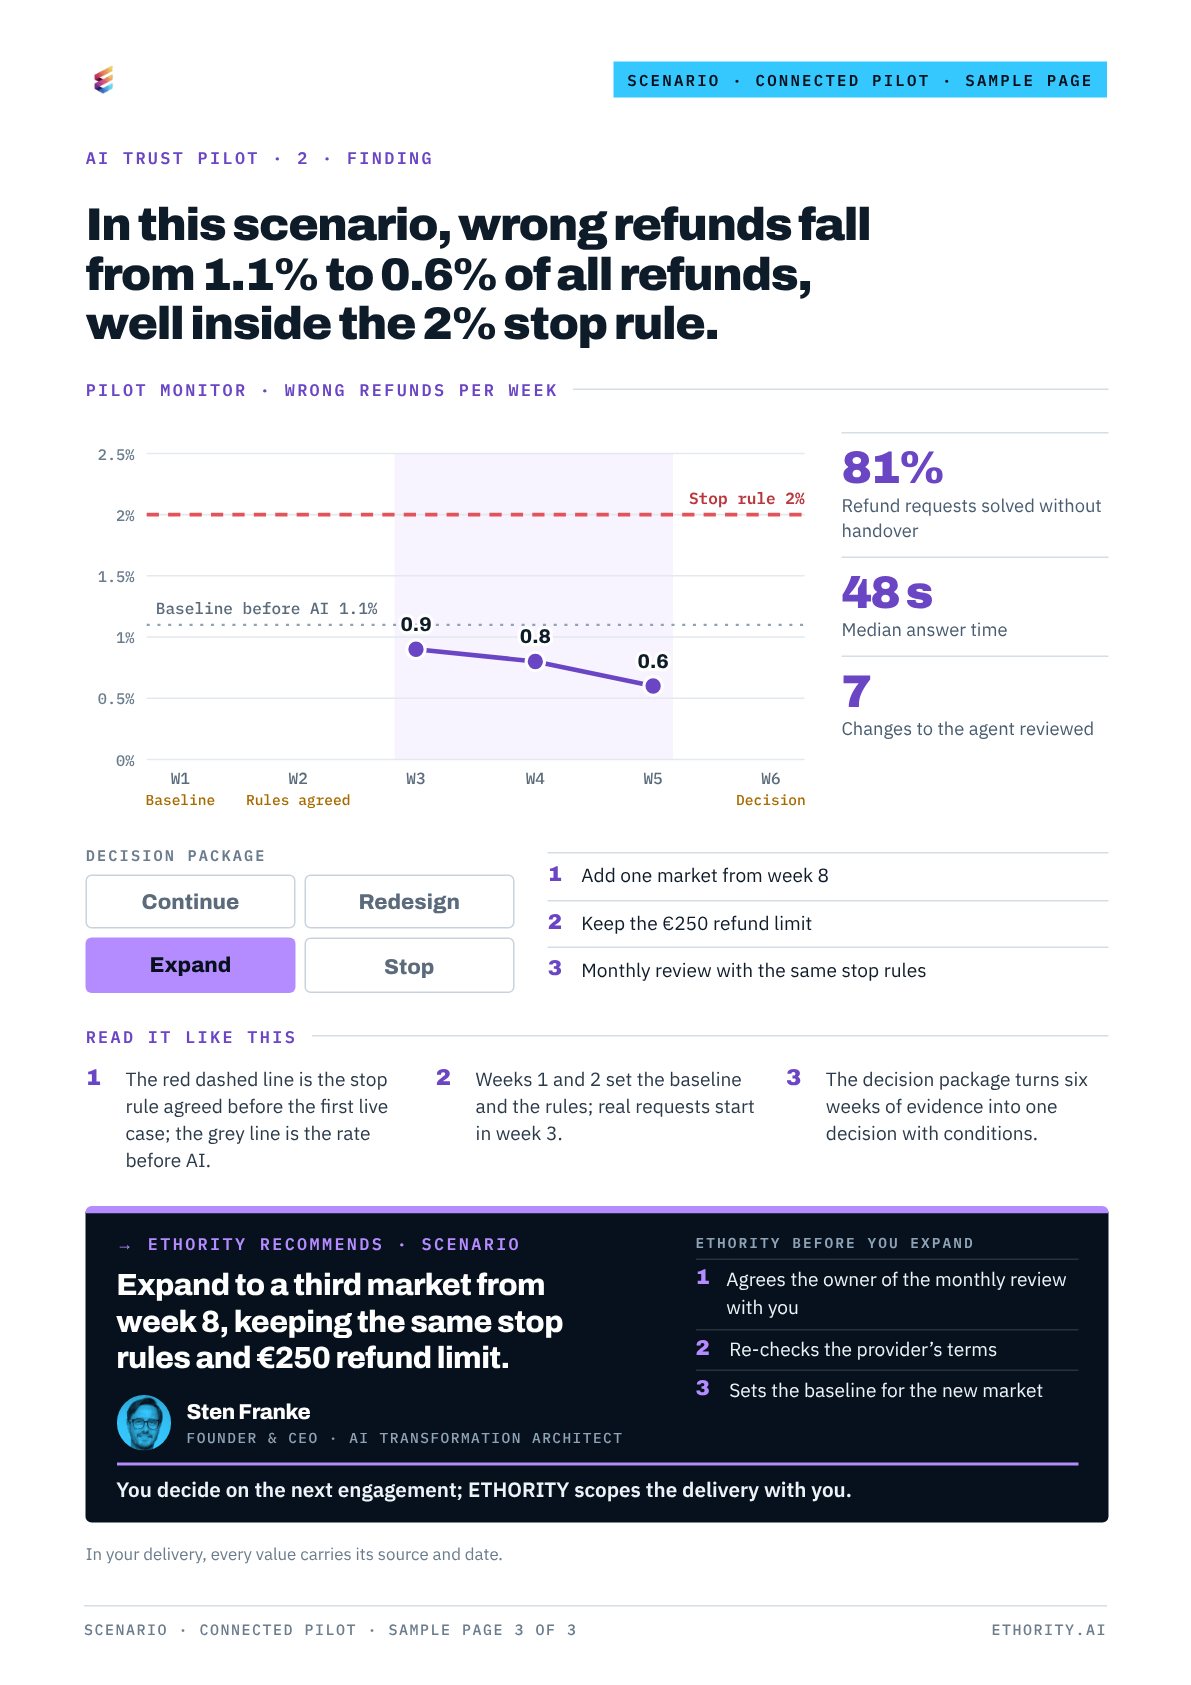
AI Trust Pilot, decision package (Scenario · connected pilot): In this scenario, wrong refunds fall from 1.1% to 0.6% of all refunds, well inside the 2% stop rule. Baseline before AI 1.1%; Stop rule 2%. Refund requests solved without handover 81%; Median answer time 48 s; Changes to the agent reviewed 7. Decision: Expand; Add one market from week 8; Keep the €250 refund limit; Monthly review with the same stop rules. ETHORITY recommends: Expand to a third market from week 8, keeping the same stop rules and €250 refund limit. You decide on the next engagement; ETHORITY scopes the delivery with you.
1 / 5 · The question
One use case. Real conditions. Six weeks.
Scenario
Read exhibit data
Scenario inputs and conditional examples; not a delivered client result or released recommendation.
AI Trust Pilot · Pilot charter · Scenario · connected pilot
Can the refund agent handle real requests for six weeks, inside agreed limits?
- Use case: Refunds up to €250
- Markets: Two
- Duration: Six weeks
See 3 sample pages · Scenario
What the deliverable looks like
Scenario: the sample shows structure, detail and questions; it is not a client result.
- Goals, limits and stop rules agreed before the start
- The AI Trust Record as the starting structure
- Documented review of changes and open points during the pilot
- A final decision: continue, redesign, expand or stop
Page 1 / 3
Read sample data
AI Trust Pilot · Sample page 1 of 3 · Scenario · connected pilot
Run one AI use case under real conditions, with stop rules agreed upfront.
Scenario: the refund agent is tested for six weeks on real requests.
Prepared by Sten Franke · ETHORITY · Six weeks
AI Trust Pilot
€25,000 net · one-time